Most DTC brands lose weeks hunting for a winning ad because they test one idea at a time and call a winner after a weekend of data. Creative testing at scale means running several distinct ad concepts at once, reading the results against a clear standard, and feeding what works back into the next batch, so a scalable ad surfaces in weeks instead of months. The brands that grow fastest on Meta and TikTok treat creative like a pipeline, not a single bet.
Targeting is mostly automated now. Machine learning decides who sees an ad, which means the ad itself carries the weight that used to sit with audience selection. A strong hook lowers cost per click and opens up cheaper reach; a weak one caps an account no matter how carefully bids are managed. This is why creative strategy, not just media buying, decides whether a brand’s ads stay profitable. If you want a structured way to find winning ads faster and stop guessing which concept will work, the framework below walks through how to build and run that system, and our team is available at (626) 509-0006 or through signalytics.ai if you’d rather have it built for you.
What Does a Repeatable Creative Testing Framework Look Like?
A repeatable creative testing framework turns scattered ad experiments into a system with clear inputs and outputs. It starts with a hypothesis, tests distinct concepts before small variations, isolates one variable when the goal is to explain a result, and organizes hooks, proof, formats, and offers into a matrix so nothing gets tested by accident.
Define the Hypothesis, Primary Outcome, and Control
Every test starts as a sentence: “We believe this audience will respond to this angle because of this insight.” Writing the hypothesis down forces a single primary outcome, whether that’s cost per acquisition, click-through rate, or conversion rate, and a control to measure against. Skipping this step turns a test into a story told after the fact.
Start with Distinct Concepts Before Refining Variations
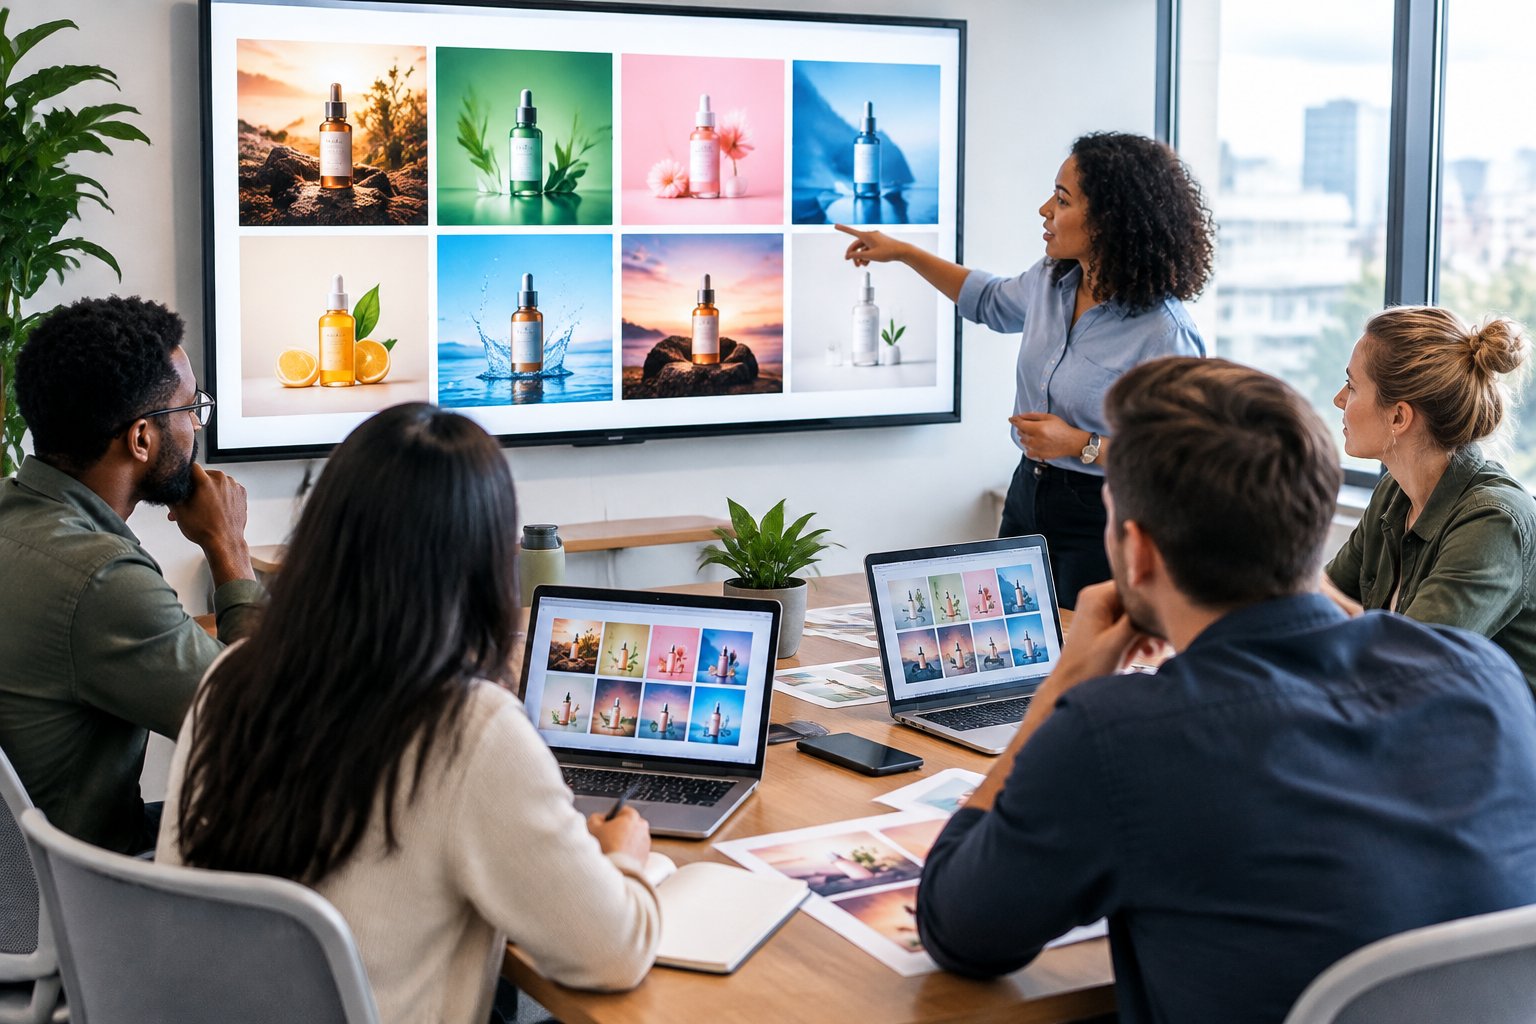
Concept testing compares genuinely different ideas, such as a testimonial video, a founder story, and a problem-agitation ad. Variation testing only makes sense after one concept proves itself, since tweaking headlines or button colors on a weak idea wastes budget. A winning concept moves results far more than a winning variation ever will.
Scaling creative doesn’t mean more shoots—this guide on getting 50 ad variations out of a single product shoot with AI shows how to multiply output from assets you already have.
Isolate Variables When You Need to Explain a Result
Once a concept wins, change one meaningful thing at a time: the hook, the visual, or the call to action, never all three together. This is how a team learns why an ad worked and can repeat it on purpose. At the concept stage, whole ads can differ across many dimensions; once a concept is chosen, variable isolation is what turns a hunch into a repeatable pattern.
Build a Test Matrix for Hooks, Proof, Formats, and Offers
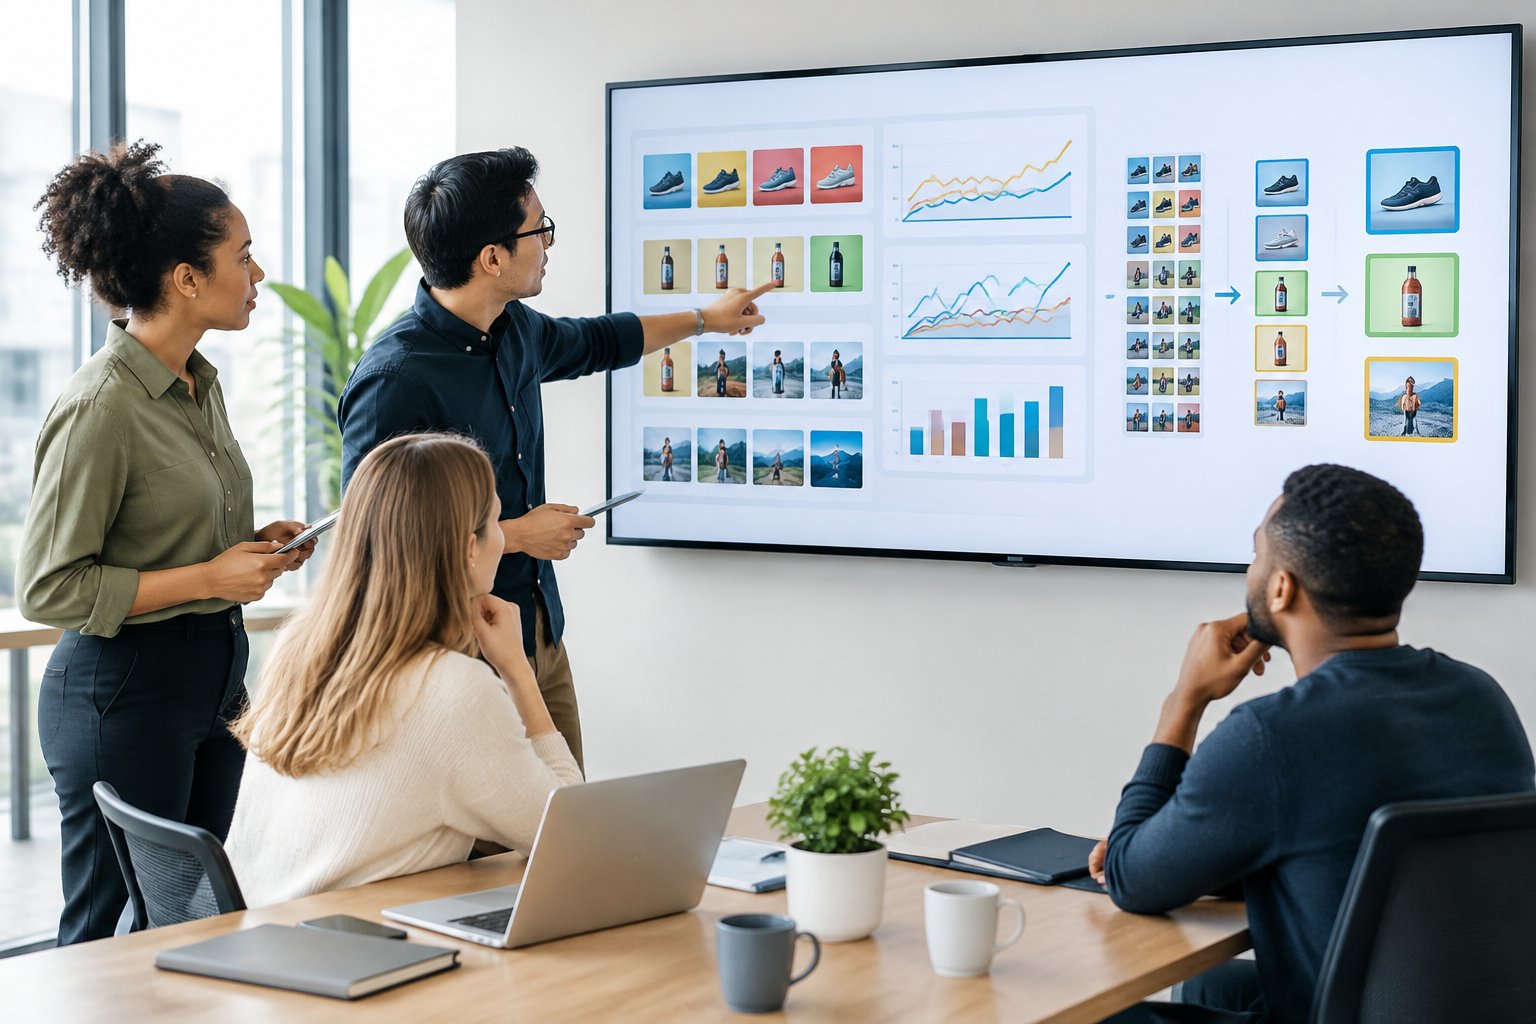
A simple grid listing hooks down one side and formats, proof points, and offers across the top keeps a testing batch organized and prevents duplicate ideas. Document which combinations have already run so the next batch adds something new instead of repeating a stale comparison. This matrix becomes the shared reference for anyone producing or reviewing creative, including teams who use ai creative testing tools to generate variants faster.
How Much Creative Can Your Testing Budget Support?
A testing budget determines how many ads can be read to a reliable result, not how many can be launched. Most accounts need roughly 50 purchase events per creative variant before a result means anything, so the math starts with cost per acquisition and works backward to figure out how many concepts fit inside a given spend.
Estimate Test Capacity from Baseline CPA and Required Evidence
If cost per acquisition runs $60 and the plan calls for 50 conversions per variant, each variant needs about $3,000 in spend before a decision is safe. A two-variant test at that CPA costs around $6,000 to read properly. Brands with a $40 CPA can run more concurrent tests on the same budget than brands with a $100 CPA, so capacity planning has to start with the actual cost per acquisition, not a flat number of ads per week.
Choose Fewer Meaningful Tests When Spend Is Limited
A smaller account running $5,000 to $15,000 a month typically supports three to six new creatives monthly, not twenty. One well-funded concept that reaches statistical significance beats five starved variants that all look inconclusive. Spreading a tight budget across too many ads produces mediocre, unreadable data for every single one.
Set Read Windows Around Conversion Lag and Buying Cycles
A test needs enough runtime to exit the platform’s learning phase and smooth out day-of-week swings, generally seven to fourteen days depending on spend. Pulling the plug after 48 hours is the most common reason good creative gets mistaken for a loser. Longer consideration cycles or slower-moving products need a longer read window before conversions catch up to spend.
Build a Creative Pipeline That Produces Useful Variety
A creative pipeline keeps new concepts entering testing before current winners fatigue, so performance doesn’t dip while a brand scrambles to produce something new. The goal is variety that teaches something, not just a larger folder of files.
Turn Customer Reviews and Competitor Research into Testable Angles
Customer reviews and support tickets hold the exact words people use to describe their problem, and those words often become the strongest hooks. Competitor ad libraries, including the Meta Ad Library, show which angles rivals keep running long-term, a sign that something is working even without access to their numbers. Mining these sources regularly keeps a team from testing the same three ideas on repeat.
Produce Modular Hooks, Product Demonstrations, and Calls to Action
Building creative in modular pieces, a library of hooks, demonstration footage, and calls to action, lets a team recombine proven parts into new ads quickly. Holding the body and offer steady while swapping only the opening three seconds is one of the most efficient ways to learn what grabs attention, since that pattern interrupt decides whether a viewer keeps watching. Our guide on what makes a high converting ad creative ai human breaks down which pieces tend to carry the most weight in that opening moment.
Use AI to Expand Production Without Losing Product Accuracy
AI creative tools can generate a batch of static ads or video variations from a single product photo far faster than a traditional shoot, which is what makes high-volume testing realistic for smaller accounts. The tradeoff is accuracy: product details, packaging, and claims still need a human check before anything launches. Our overview of ai ad creative how to scale creative testing covers how to use generation tools without sacrificing that accuracy.
Tag Every Asset So Results Inform the Next Brief
Every creative needs a record of its concept, hook, format, and result, stored somewhere the whole team can see. Without this, a brand repeats the same losing idea under a different name six months later. A shared tracking sheet or lightweight database turns individual tests into compounding knowledge.
How Should You Launch Tests on Meta and TikTok?
Launching a test cleanly on Meta or TikTok means choosing a testing method that matches the question being asked, then protecting that test from interference by the platform’s own automation. Getting this setup wrong is a common reason good creative gets buried before it has a fair shot.
Choose Controlled Split Tests or Algorithm-Led Exploration
Meta’s Experiments and TikTok’s Split Test tools divide an audience into non-overlapping groups for a clean read on one variable, which is the right call when a team needs to know exactly why an ad won. Placing three to five ads in a single ad set and letting the algorithm allocate spend works faster for early concept discovery, though the algorithm tends to pick a favorite before the data is fully conclusive. A practical approach runs new concepts in a single ad set first, then validates the top performer with a proper split test before committing real budget.
Decide When to Separate Testing and Scaling Campaigns
Testing and scaling campaigns should run separately so a losing experiment never drags down a proven winner’s ad set. The testing campaign tolerates volatility because the goal is learning; the scaling campaign protects performance because the goal is profit. Mixing the two muddies both and can trigger Advantage+ or dynamic creative tools to reshuffle budget in ways that are hard to untangle later.
Adapt Creative to Each Platform and Placement
A format that works on Meta feed rarely performs the same way on TikTok, where native, less polished content tends to hold attention longer. Our breakdown of ai creative for meta vs tiktok vs amazon what changes covers how hook style, pacing, and visual tone shift across platforms, and the tiktok ads management guide covers platform-specific setup in more depth.
Keep Tracking, Offers, and Destination Experiences Consistent
Comparing ads under different attribution windows or sending traffic to inconsistent landing page experiences makes results impossible to trust. The offer, pixel setup, and destination page should stay fixed while creative is the only thing that changes. This is the detail that keeps a machine learning-optimized campaign from generating misleading signals during its learning phase.
How Do You Decide Which Ads to Scale, Iterate, or Stop?
An ad is ready to scale when it beats the control on cost per result with enough conversions behind it to trust the number, usually a minimum of 50 purchase events per variant. Reading metrics as a funnel, from attention down to conversion, shows whether an underperforming ad needs a new hook or a completely different concept.
Separate Attention Metrics from Profitable Conversion Outcomes
Hook rate, hold rate, and the 3-second view rate measure attention; cost per result and ROAS measure whether that attention turns into profit. A high click-through rate paired with poor ROAS usually points to a landing page or offer problem, not a creative failure. Reading these layers in order shows exactly which part of the ad needs fixing.
| Metric | What it reveals | Trust level at low volume |
|---|---|---|
| Hook rate / 3-second view rate | Whether the opening stops the scroll | Reliable after a few thousand impressions |
| Click-through rate | Whether the message drives interest | Reliable after a few hundred clicks |
| Cost per result / ROAS | Whether the ad is profitable | Reliable after roughly 50 conversions |
Check Sample Size, Attribution, and Delivery Bias Before Declaring Winners
A 3% difference in click-through rate on a small sample is noise, not a winner. Checking that each variant reached a similar delivery volume, that attribution settings matched across ads, and that the test ran long enough to exit the learning phase prevents a false win from getting scaled.
Use a Decision Scorecard to Scale, Revise, Pause, or Keep Testing
A simple scorecard sorts every tested ad into one of four categories: scale (beats the target with enough data), revise (promising hook, weak conversion), pause (clearly underperforming after a fair read), or keep testing (inconclusive, needs more spend or time). Writing these rules before launch keeps the decision boring instead of emotional.
Diagnose Creative Fatigue Without Ignoring Other Performance Changes
Creative fatigue shows up as rising frequency, declining click-through rate, and climbing cost per acquisition on an ad that used to perform well. Before blaming fatigue, check whether CPMs rose across the account or a seasonal shift hit conversion rate broadly, since those changes can mimic fatigue on ads that are still sound. Our piece on maximize roas thinking outside data covers how to separate a true creative problem from a wider account trend.
Carry Winning Messages Through to Landing Pages and Amazon Listings
A winning hook or angle should show up in the landing page headline and, for Amazon sellers, in listing copy and imagery too. Our article on the secret to conversions amazon experiments covers how listing-level testing mirrors this same discipline. Messages that convert in an ad usually convert again when carried through to the page that closes the sale.
Make Each Test Improve the Next Creative Brief
Creative testing pays off when every test result becomes an input for the next brief instead of a closed file. A pipeline that documents what won, what failed, and why turns a one-time lucky ad into a repeatable source of winning ads. Over time, the tagged library of hooks, formats, and offers becomes the fastest shortcut a team has for building the next batch, since nothing has to start from a blank page.
Frequently Asked Questions
How many ad creatives should I test at once?
The right number scales with monthly ad spend: accounts under $10,000 a month typically test one to three new concepts monthly, while accounts spending $50,000 to $100,000 can support two to four new concepts a week. The limiting factor is always whether each variant can reach enough conversions to produce a readable result, not a fixed quota.
How long should a creative test run before I choose a winner?
Most tests need seven to fourteen days to clear the platform’s learning phase and collect enough conversions per variant. Calling a winner after two or three days almost always reflects early randomness rather than a real performance gap.
Is $10 a day enough to test Facebook ads?
Ten dollars a day can launch a test, but it rarely generates enough conversions to reach statistical significance within a reasonable window. A test at that budget level works better for directional signals on upper-funnel metrics like click-through rate than for a confident go or no-go decision on conversion-based results.
What is the 3-2-2 method of Facebook ads, and is it a controlled test?
The 3-2-2 method refers to running three ad sets, each with two ads, testing two audiences or variables. It is closer to algorithm-led exploration than a strictly controlled test, since ads inside a shared ad set compete for the same budget rather than being isolated the way a formal A/B test would separate them.
How can I use the Meta Ad Library to find creative testing ideas?
The Meta Ad Library shows which ads competitors are running and for how long, and an ad that has stayed active for weeks is a signal it’s performing well for its advertiser. Reviewing these ads for recurring angles, formats, or offers can surface concepts worth testing, without copying the creative itself.